Didi Zhu

Postdoctoral Research Associate

Department
Computing
Based in
London, UK
Photo of Didi Zhu

Research

I work on post-training large multimodal models: reinforcement learning for reasoning and perception, verifiable rewards, and the data and evaluation pipelines behind open model releases. A growing part of my work is on multimodal agents and generation.

About

I am currently a Postdoctoral Research Associate at Imperial College London, working with Prof. Jiankang Deng and Prof. Stefanos Zafeiriou. I received my Ph.D. from Zhejiang University, advised by Prof. Chao Wu and co-supervised by Prof. Kun Kuang and Prof. Fei Wu, and was fortunate to collaborate with Yibing Song at Alibaba DAMO Academy.

Research

A path from making vision–language models robust, to composing their skills, to teaching them to reason, and now to connecting understanding with generation.

Hover a direction to explore

  1. 012021–2024

    Align

    Robust vision–language models

    Using structure and theory (neural collapse, attention matching, generative flow networks) to make vision–language models generalize beyond the distributions they were trained on.

    8 papers
  2. 022024–2025

    Compose

    Merging, forgetting and reuse

    Understanding how multimodal models forget, merge and reuse specialized skills during post-training, so capabilities can be added without losing old ones.

    9 papers
  3. 032025–now

    Reason

    RL for multimodal reasoning

    Eliciting reliable reasoning and perception with reinforcement learning and verifiable rewards, and building the data and evaluation pipelines behind open model releases.

    6 papers
  4. 042025–now

    Generate

    Understanding meets generation

    Using understanding models as data engines, reward models and evaluators for generative models, and bringing RL to flow-based visual generation.

    5 papers

Experience

  1. Education

    Sep 2016 – Jun 2020

    Beijing University of Chemical Technology

    B.S. in Computer Science and Technology

  2. Education

    Sep 2020 – Jun 2025

    Zhejiang University

    Ph.D. in Computer Science and Technology

    Advised by Prof. Chao Wu, co-supervised by Prof. Kun Kuang and Prof. Fei Wu.

  3. Industry

    Oct 2023 – Feb 2024

    Tencent Youtu Lab

    Research Intern, Multimodal LLMs

    With Zhongyi Sun. Led to Model Tailor (ICML 2024).

  4. Industry

    Mar 2024 – Mar 2025

    Alibaba DAMO Academy

    Research Intern, Multimodal LLMs

    With Yibing Song. Led to REMEDY (ICLR 2025).

  5. PositionNow

    Sep 2025 – now

    Imperial College London

    Postdoctoral Research Associate

    Working with Prof. Jiankang Deng and Prof. Stefanos Zafeiriou.

News

  1. Paper

    AdaViG accepted to NeurIPS 2026: a training-free gate that decides when a unified multimodal model should draw while it reasons.

  2. Release

    Released VisualFLIP (first author), a paired benchmark that tests whether MLLM predictions actually depend on task-critical visual evidence.

  3. Paper

    Co-author paper on flow-based GRPO for visual generation accepted to ICML 2026.

  4. Release

    Released LLaVA-OneVision-2, an open 8B multimodal foundation model unifying image, long-video and spatial understanding. I served as a core contributor.

  5. Release

    Released LLaVA-OneVision-1.5-RL, a fully open recipe for lightweight multimodal RL. I led the RL section as first author.

  6. Career

    Joined Imperial College London as a Postdoctoral Research Associate, working with Prof. Jiankang Deng and Prof. Stefanos Zafeiriou.

  7. Paper

    First-author paper Watch Wider and Think Deeper accepted to the NeurIPS 2025 Workshop on Multimodal Algorithmic Reasoning.

  8. Paper

    Co-author paper Mix Data or Merge Models? accepted to NeurIPS 2025.

  9. Paper

    Co-author papers accepted to ICCV 2025 (text-to-image misalignment) and KDD 2025 (FedGuCci).

  10. Career

    Received my Ph.D. in Computer Science and Technology from Zhejiang University.

  11. Paper

    Four co-author papers accepted to ICML 2025.

  12. Travel

    Attended ICLR 2025 in Singapore.

  13. Paper

    Co-author paper accepted to the ICLR 2025 FL Workshop.

  14. Paper

    Three papers accepted to ICLR 2025, including first-author REMEDY.

  15. Travel

    Attended ICML 2024 in Vienna, Austria.

  16. Paper

    First-author paper Model Tailor accepted to ICML 2024.

  17. Paper

    First-author paper Neural Collapse Anchored Prompt Tuning accepted to KDD 2024.

  18. Travel

    Attended ICCV 2023 in Paris, France.

  19. Paper

    First-author paper Universal Domain Adaptation via Compressive Attention Matching accepted to ICCV 2023.

  20. Paper

    First-author paper Generalized Universal Domain Adaptation with Generative Flow Networks accepted to ACM MM 2023.

  21. Paper

    Co-author paper accepted to KDD 2023.

  22. Paper

    Co-author paper accepted to IEEE Transactions on Big Data.

  23. Paper

    Co-author paper accepted to the IJCAI 2021 FL Workshop (FTL-IJCAI).

Projects

Open multimodal model releases I have worked on, with code, data and checkpoints.

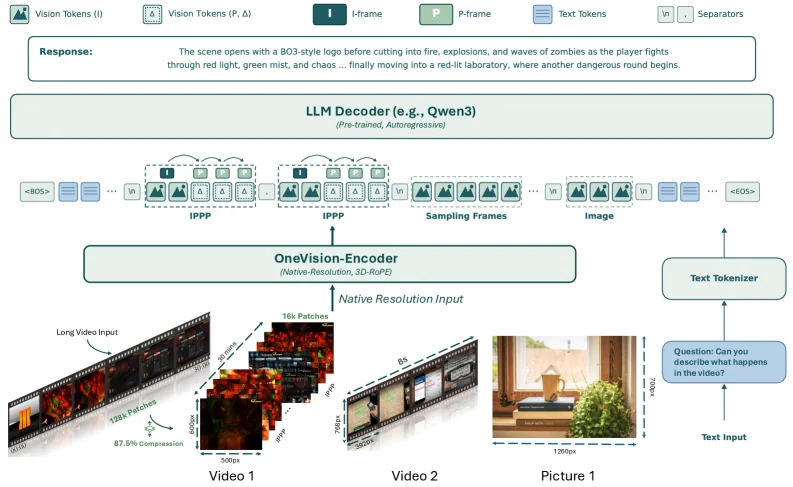
LLaVA-OneVision-2 architecture: the OneVision-Encoder turns native-resolution images and long videos, as I- and P-frame tokens, into vision tokens for an LLM decoder.
Tech Report 2026 Core contributor

LLaVA-OneVision-2: Towards Next-Generation Perceptual Intelligence

Xiang An, Yin Xie, Feilong Tang, Yunyao Yan, Huajie Tan, Didi Zhu, Changrui Chen, Xiuwei Zhao, Bin Qin, Kaicheng Yang, et al.

An open 8B model unifying image, long-video and spatial understanding. I worked on the video data engine and evaluation.

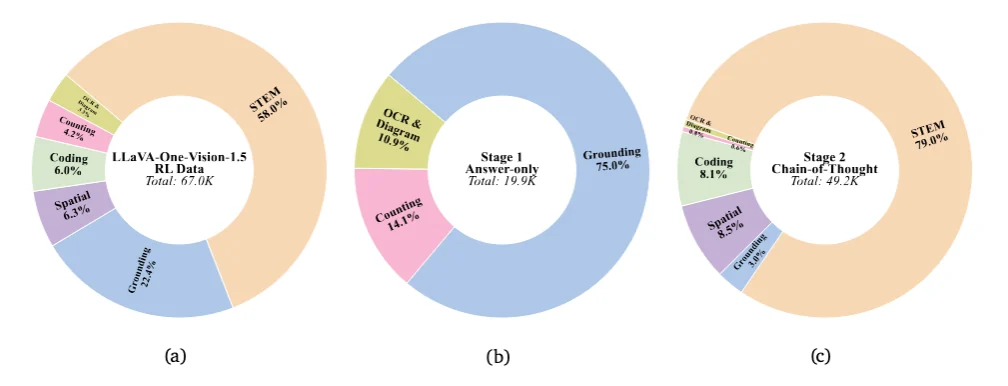
Donut charts of the 67K-example RL training set by task category: an answer-only first stage and a chain-of-thought second stage dominated by STEM.
Tech Report 2025 First author · RL section

LLaVA-OneVision-1.5-RL: Unlocking Multimodal Reasoning via Lightweight Reinforcement Learning

Didi Zhu, Zhiyu Qu, Zerui Chen, Polydefkis Gkagkos, Xiang An, Bo Li

Lightweight two-stage GRPO on 67K difficulty-filtered examples, with clear gains on STEM, coding and reasoning.

Publications

Selected first-author papers, then everything, newest first. Google Scholar has citation counts.

Selected

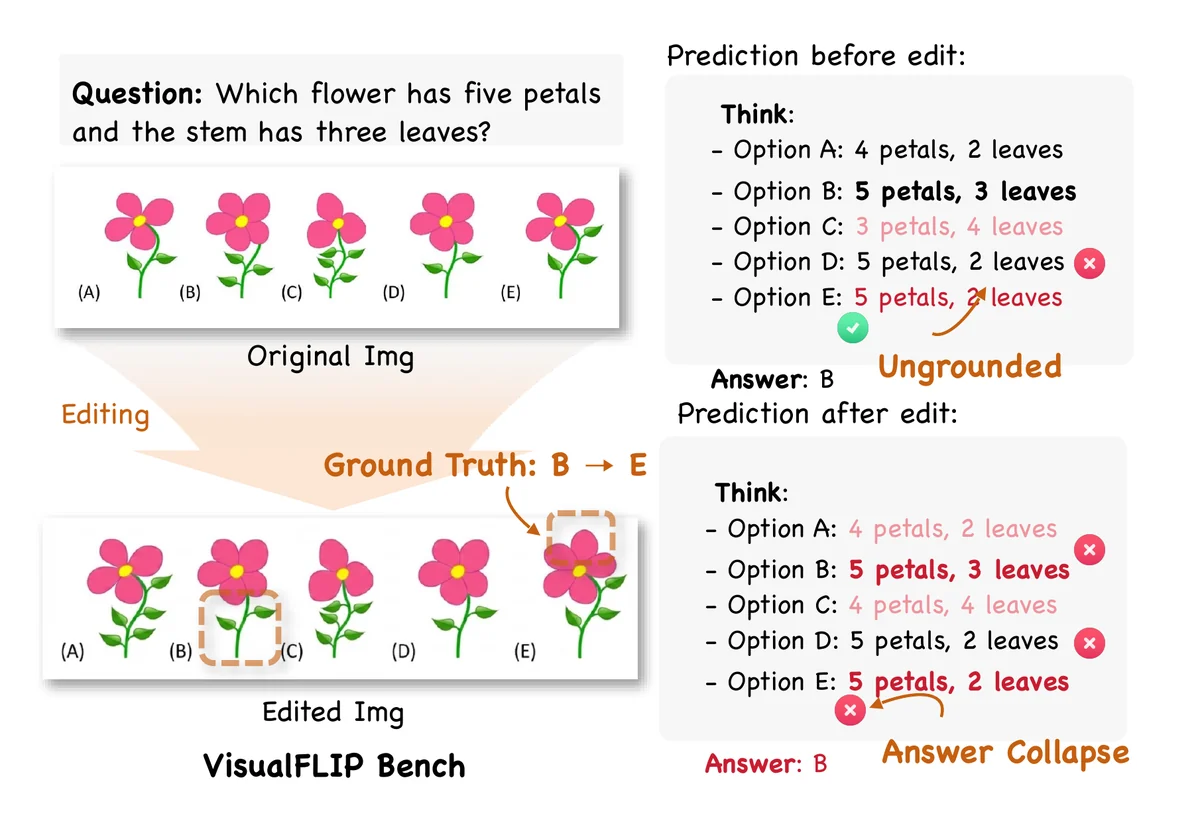
VisualFLIP example: after a minimal edit flips the correct option from B to E, the model keeps answering B.
arXiv 2026 First author

VisualFLIP: Do Predictions Depend on Task-Critical Visual Evidence in Multimodal Reasoning?

Didi Zhu, Changrui Chen, Stefanos Zafeiriou, Jiankang Deng

A paired benchmark of 1,374 images that tests whether MLLM answers change when the task-critical visual evidence changes.

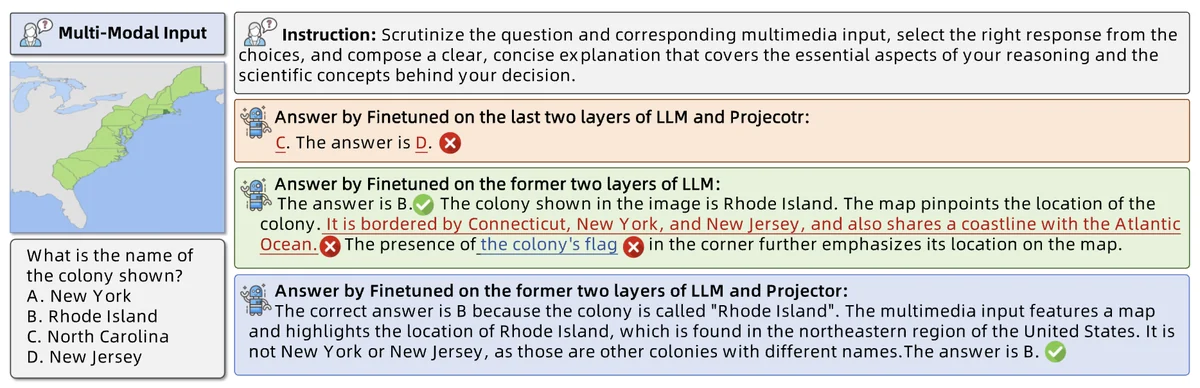
REMEDY example: answers to a map question change with which layers were fine-tuned; tuning the projector and shallow LLM layers gives the right answer.
ICLR 2025 First author

REMEDY: Recipe Merging Dynamics in Large Vision-Language Models

Didi Zhu, Yibing Song, Tao Shen, Ziyu Zhao, Jinluan Yang, Min Zhang, Chao Wu

Merges reusable modules of vision–language models with input-aware weights, improving both multi-task and zero-shot performance.

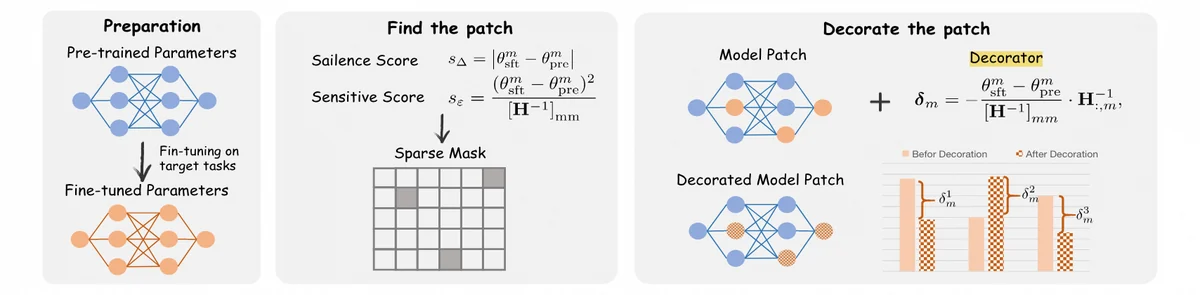
Model Tailor framework: find a sparse patch of fine-tuned parameters with salience and sensitivity scores, then decorate the patch with a compensation term.
ICML 2024 First author

Model Tailor: Mitigating Catastrophic Forgetting in Multi-modal Large Language Models

Didi Zhu, Zhongyi Sun, Zexi Li, Tao Shen, Ke Yan, Shouhong Ding, Kun Kuang, Chao Wu

A training-free fix for catastrophic forgetting in MLLMs: graft a small patch of fine-tuned weights onto the pre-trained model.

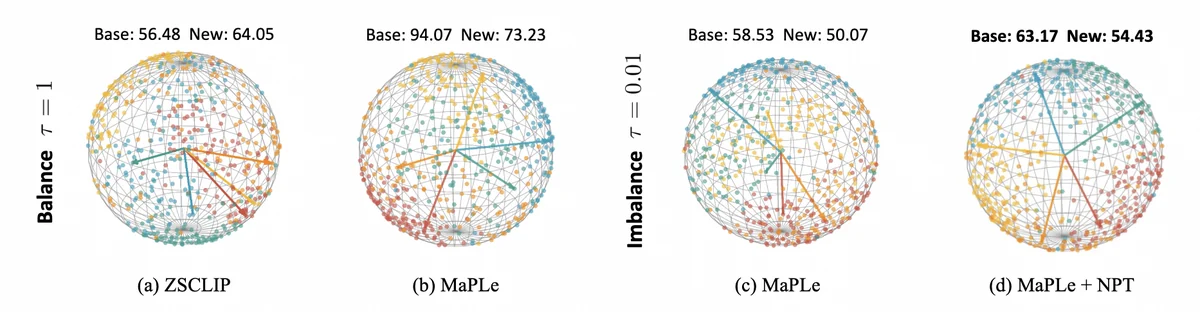
Neural collapse in CLIP on EuroSAT: text and image representations on a sphere, under balanced and imbalanced data, with and without NPT.
KDD 2024 First author

Neural Collapse Anchored Prompt Tuning for Generalizable Vision-Language Models

Didi Zhu, Zexi Li, Min Zhang, Junkun Yuan, Jiashuo Liu, Kun Kuang, Chao Wu

Studies prompt tuning of vision–language models through the lens of neural collapse, and uses it to keep them generalizing under class imbalance.

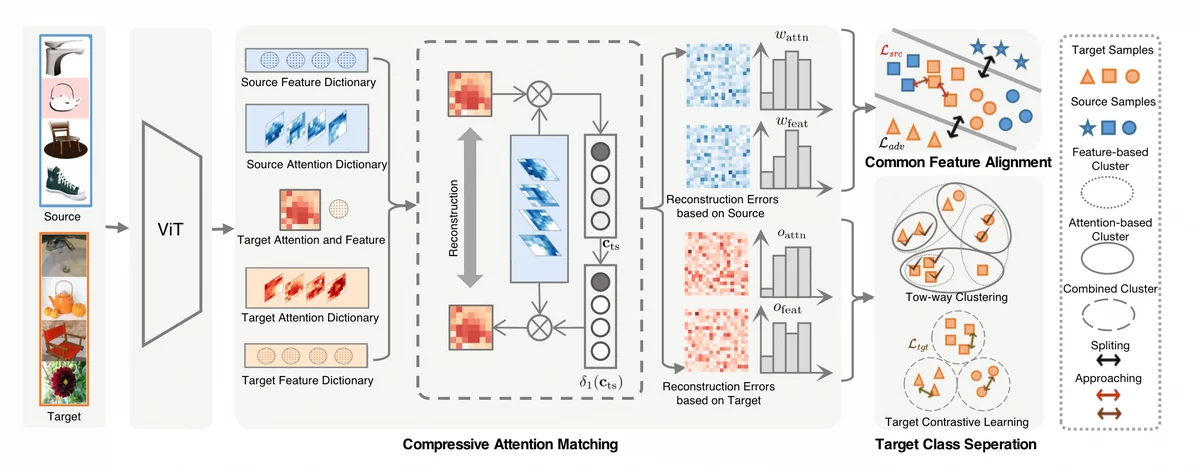
UniAM framework: compressive attention matching on ViT attention, with common feature alignment and target class separation.
ICCV 2023 First author

Universal Domain Adaptation via Compressive Attention Matching

Didi Zhu, Yinchuan Li, Junkun Yuan, Zexi Li, Kun Kuang, Chao Wu

Handles mismatched source and target label spaces in universal domain adaptation directly with ViT self-attention, via compressive attention matching.

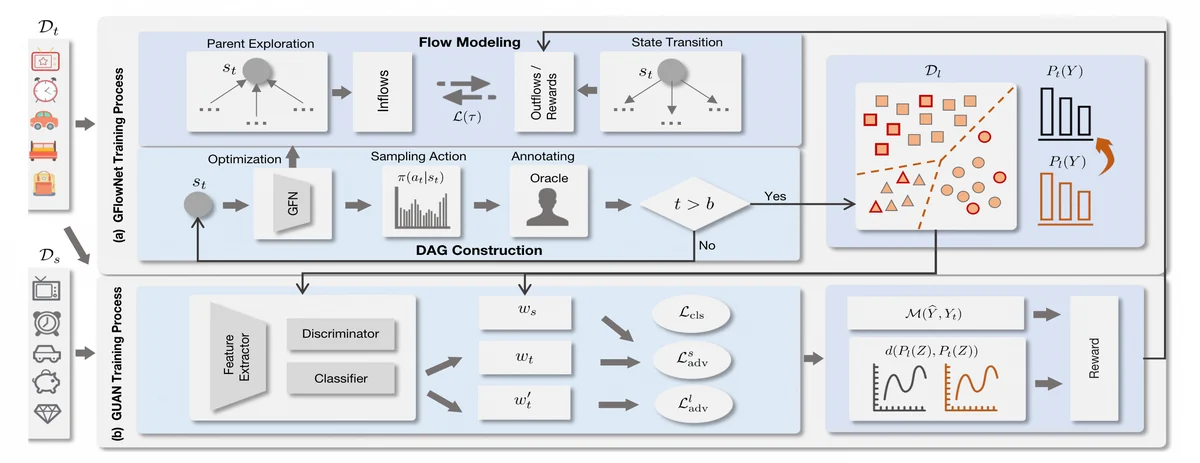
GFlowDA framework: a GFlowNet selects and labels target samples that train the adaptation network, which returns a reward.
ACM MM 2023 First author

Generalized Universal Domain Adaptation with Generative Flow Networks

Didi Zhu, Yinchuan Li, Yunfeng Shao, Jianye Hao, Fei Wu, Kun Kuang, Jun Xiao, Chao Wu

Introduces generalized universal domain adaptation, unifying the label-heterogeneity variants of domain adaptation, and tackles it with exploration-aware active learning based on generative flow networks.

All publications

2026

  1. NeurIPS 2026
    Model Guides You How to Draw: Adaptive Visual Gating for Unified Multimodal Reasoning

    Wenxi Gao, Guanxi Lu, Didi Zhu, Hao Mark Chen, Quan Deng, Zhican Wang, Jiankang Deng, Hongxiang Fan

  2. arXiv 2026
    VisualFLIP: Do Predictions Depend on Task-Critical Visual Evidence in Multimodal Reasoning?

    Didi Zhu, Changrui Chen, Stefanos Zafeiriou, Jiankang Deng

  3. Tech Report 2026
    LLaVA-OneVision-2: Towards Next-Generation Perceptual Intelligence

    Xiang An, Yin Xie, Feilong Tang, Yunyao Yan, Huajie Tan, Didi Zhu, Changrui Chen, Xiuwei Zhao, Bin Qin, Kaicheng Yang, et al.

  4. ICML 2026
    Alleviating Sparse Rewards by Modeling Step-Wise and Long-Term Sampling Effects in Flow-Based GRPO

    Yunze Tong, Mushui Liu, Canyu Zhao, Didi Zhu, Wanggui He, Shiyi Zhang, Hongwei Zhang, Peng Zhang, Jinlong Liu, Hao Jiang

  5. KDD 2026
    Each Rank Could be an Expert: Single-Ranked Mixture of Experts LoRA for Multi-Task Learning

    Ziyu Zhao, Yixiao Zhou, Zhi Zhang, Didi Zhu, Tao Shen, Zexi Li, Jinluan Yang, Xuwu Wang, Jing Su, Kun Kuang, Zhongyu Wei, Fei Wu, Yu Cheng

  6. arXiv 2026
    InfinityEdit: Infinite Video Editing with a Lightweight Edit-Ignition Adapter

    Yunze Tong, Mushui Liu, Canyu Zhao, Shiyi Zhang, Didi Zhu, Peng Zhang, Wanggui He, Jinlong Liu, Ying Chen, Hao Jiang, Pipei Huang, Bo Zheng

2025

  1. Tech Report 2025
    LLaVA-OneVision-1.5-RL: Unlocking Multimodal Reasoning via Lightweight Reinforcement Learning

    Didi Zhu, Zhiyu Qu, Zerui Chen, Polydefkis Gkagkos, Xiang An, Bo Li

  2. Tech Report 2025
    LLaVA-OneVision-1.5: Fully Open Framework for Democratized Multimodal Training

    Xiang An, Yin Xie, Kaicheng Yang, Wenkang Zhang, Xiuwei Zhao, Zheng Cheng, Yirui Wang, Songcen Xu, Changrui Chen, Didi Zhu, et al.

  3. NeurIPS 2025 Workshop
    Watch Wider and Think Deeper: Collaborative Cross-modal Chain-of-Thought for Complex Visual Reasoning

    Wenting Lu*, Didi Zhu*, Tao Shen, Donglin Zhu, Ayong Ye, Chao Wu · *equal contribution

  4. ICCV 2025
    Decoding Correlation-Induced Misalignment in the Stable Diffusion Workflow for Text-to-Image Generation

    Yunze Tong, Fengda Zhang, Didi Zhu, Jun Xiao, Kun Kuang

  5. arXiv 2025
    Noise Projection: Closing the Prompt-Agnostic Gap Behind Text-to-Image Misalignment in Diffusion Models

    Yunze Tong, Didi Zhu, Zijing Hu, Jinluan Yang, Ziyu Zhao

  6. NeurIPS 2025
    Mix Data or Merge Models? Balancing the Helpfulness, Honesty, and Harmlessness of Large Language Model via Model Merging

    Jinluan Yang, Dingnan Jin, Anke Tang, Li Shen, Didi Zhu, Zhengyu Chen, Ziyu Zhao, Daixin Wang, Qing Cui, Zhiqiang Zhang, Jun Zhou, Fei Wu, Kun Kuang

  7. ICML 2025
    ERICT: Enhancing Robustness by Identifying Concept Tokens in Zero-Shot Vision Language Models

    Xinpeng Dong, Min Zhang, Didi Zhu, Ye Jun Jian, Keli Zhang, Aimin Zhou, Fei Wu, Kun Kuang

  8. ICML 2025
    ZeroFlow: Overcoming Catastrophic Forgetting is Easier than You Think

    Tao Feng, Wei Li, Didi Zhu, Hangjie Yuan, Wendi Zheng, Dan Zhang, Jie Tang

  9. ICML 2025
    Learn from Downstream and Be Yourself in Multimodal Large Language Model Fine-Tuning

    Wenke Huang, Jian Liang, Zekun Shi, Didi Zhu, Guancheng Wan, He Li, Bo Du, Dacheng Tao, Mang Ye

  10. ICML 2025
    Be Confident: Uncovering Overfitting in MLLM Multi-Task Tuning

    Wenke Huang, Jian Liang, Guancheng Wan, Didi Zhu, He Li, Jiawei Shao, Mang Ye, Bo Du, Dacheng Tao

  11. ICLR 2025
    REMEDY: Recipe Merging Dynamics in Large Vision-Language Models

    Didi Zhu, Yibing Song, Tao Shen, Ziyu Zhao, Jinluan Yang, Min Zhang, Chao Wu

  12. ICLR 2025
    Mitigating the Backdoor Effect for Multi-Task Model Merging via Safety-Aware Subspace

    Jinluan Yang, Anke Tang, Didi Zhu, Zhengyu Chen, Li Shen, Fei Wu

  13. ICLR 2025
    Merging LoRAs like Playing LEGO: Pushing the Modularity of LoRA to Extremes Through Rank-Wise Clustering

    Ziyu Zhao, Tao Shen, Didi Zhu, Zexi Li, Jing Su, Xuwu Wang, Kun Kuang, Fei Wu

  14. KDD 2025
    FedGuCci: Making Local Models More Connected in Landscape for Federated Learning

    Zexi Li, Jie Lin, Zhiqi Li, Didi Zhu, Tao Shen, Tao Lin, Chao Wu, Nicholas D. Lane

  15. arXiv 2025
    Will LLMs Scaling Hit the Wall? Breaking Barriers via Distributed Resources on Massive Edge Devices

    Tao Shen*, Didi Zhu*, Ziyu Zhao*, Zexi Li, Chao Wu, Fei Wu · *equal contribution

2024

  1. ICML 2024
    Model Tailor: Mitigating Catastrophic Forgetting in Multi-modal Large Language Models

    Didi Zhu, Zhongyi Sun, Zexi Li, Tao Shen, Ke Yan, Shouhong Ding, Kun Kuang, Chao Wu

  2. KDD 2024
    Neural Collapse Anchored Prompt Tuning for Generalizable Vision-Language Models

    Didi Zhu, Zexi Li, Min Zhang, Junkun Yuan, Jiashuo Liu, Kun Kuang, Chao Wu

2023

  1. ICCV 2023
    Universal Domain Adaptation via Compressive Attention Matching

    Didi Zhu, Yinchuan Li, Junkun Yuan, Zexi Li, Kun Kuang, Chao Wu

  2. ACM MM 2023
    Generalized Universal Domain Adaptation with Generative Flow Networks

    Didi Zhu, Yinchuan Li, Yunfeng Shao, Jianye Hao, Fei Wu, Kun Kuang, Jun Xiao, Chao Wu

  3. KDD 2023
    Quantitatively Measuring and Contrastively Exploring Heterogeneity for Domain Generalization

    Yunze Tong, Junkun Yuan, Min Zhang, Didi Zhu, Keli Zhang, Fei Wu, Kun Kuang

2022

  1. IEEE TBD 2022
    Towards Effective Clustered Federated Learning: A Peer-to-peer Framework with Adaptive Neighbor Matching

    Zexi Li, Jiaxun Lu, Shuang Luo, Didi Zhu, Yunfeng Shao, Yinchuan Li, Zhimeng Zhang, Yongheng Wang, Chao Wu

2021

  1. IJCAI 2021 Workshop
    Ensemble Federated Adversarial Training with Non-IID Data

    Shuang Luo, Didi Zhu, Zexi Li, Chao Wu

Honors & Service

Honors

  • 2024 National Scholarship Ph.D. · top 5%
  • 2020 Beijing Outstanding Graduate Top 1%
  • 2017–2019 National Scholarship, three times Undergraduate · top 1%

Service

Conference reviewer

  • CVPR
  • ECCV
  • ICCV
  • ICLR
  • NeurIPS
  • KDD
  • ACM MM

Journal reviewer

  • IEEE TIP
  • Machine Learning